See exactly how
you work with Claude.
Claude Radar reads your real project conversations and surfaces your collaboration blind spots across 9 dimensions in 3 categories — Communication, Engineering, Outcome — with Engineering looking at how far you push Claude Code's platform leverage (Skill / MCP / Subagent / CLAUDE.md / Plan). Beyond the scores, it writes a diagnosis that actually pins down your habits, plus at least 5 rewrite prompts you can paste straight into your next session. Work smoother next time — and level up for real.
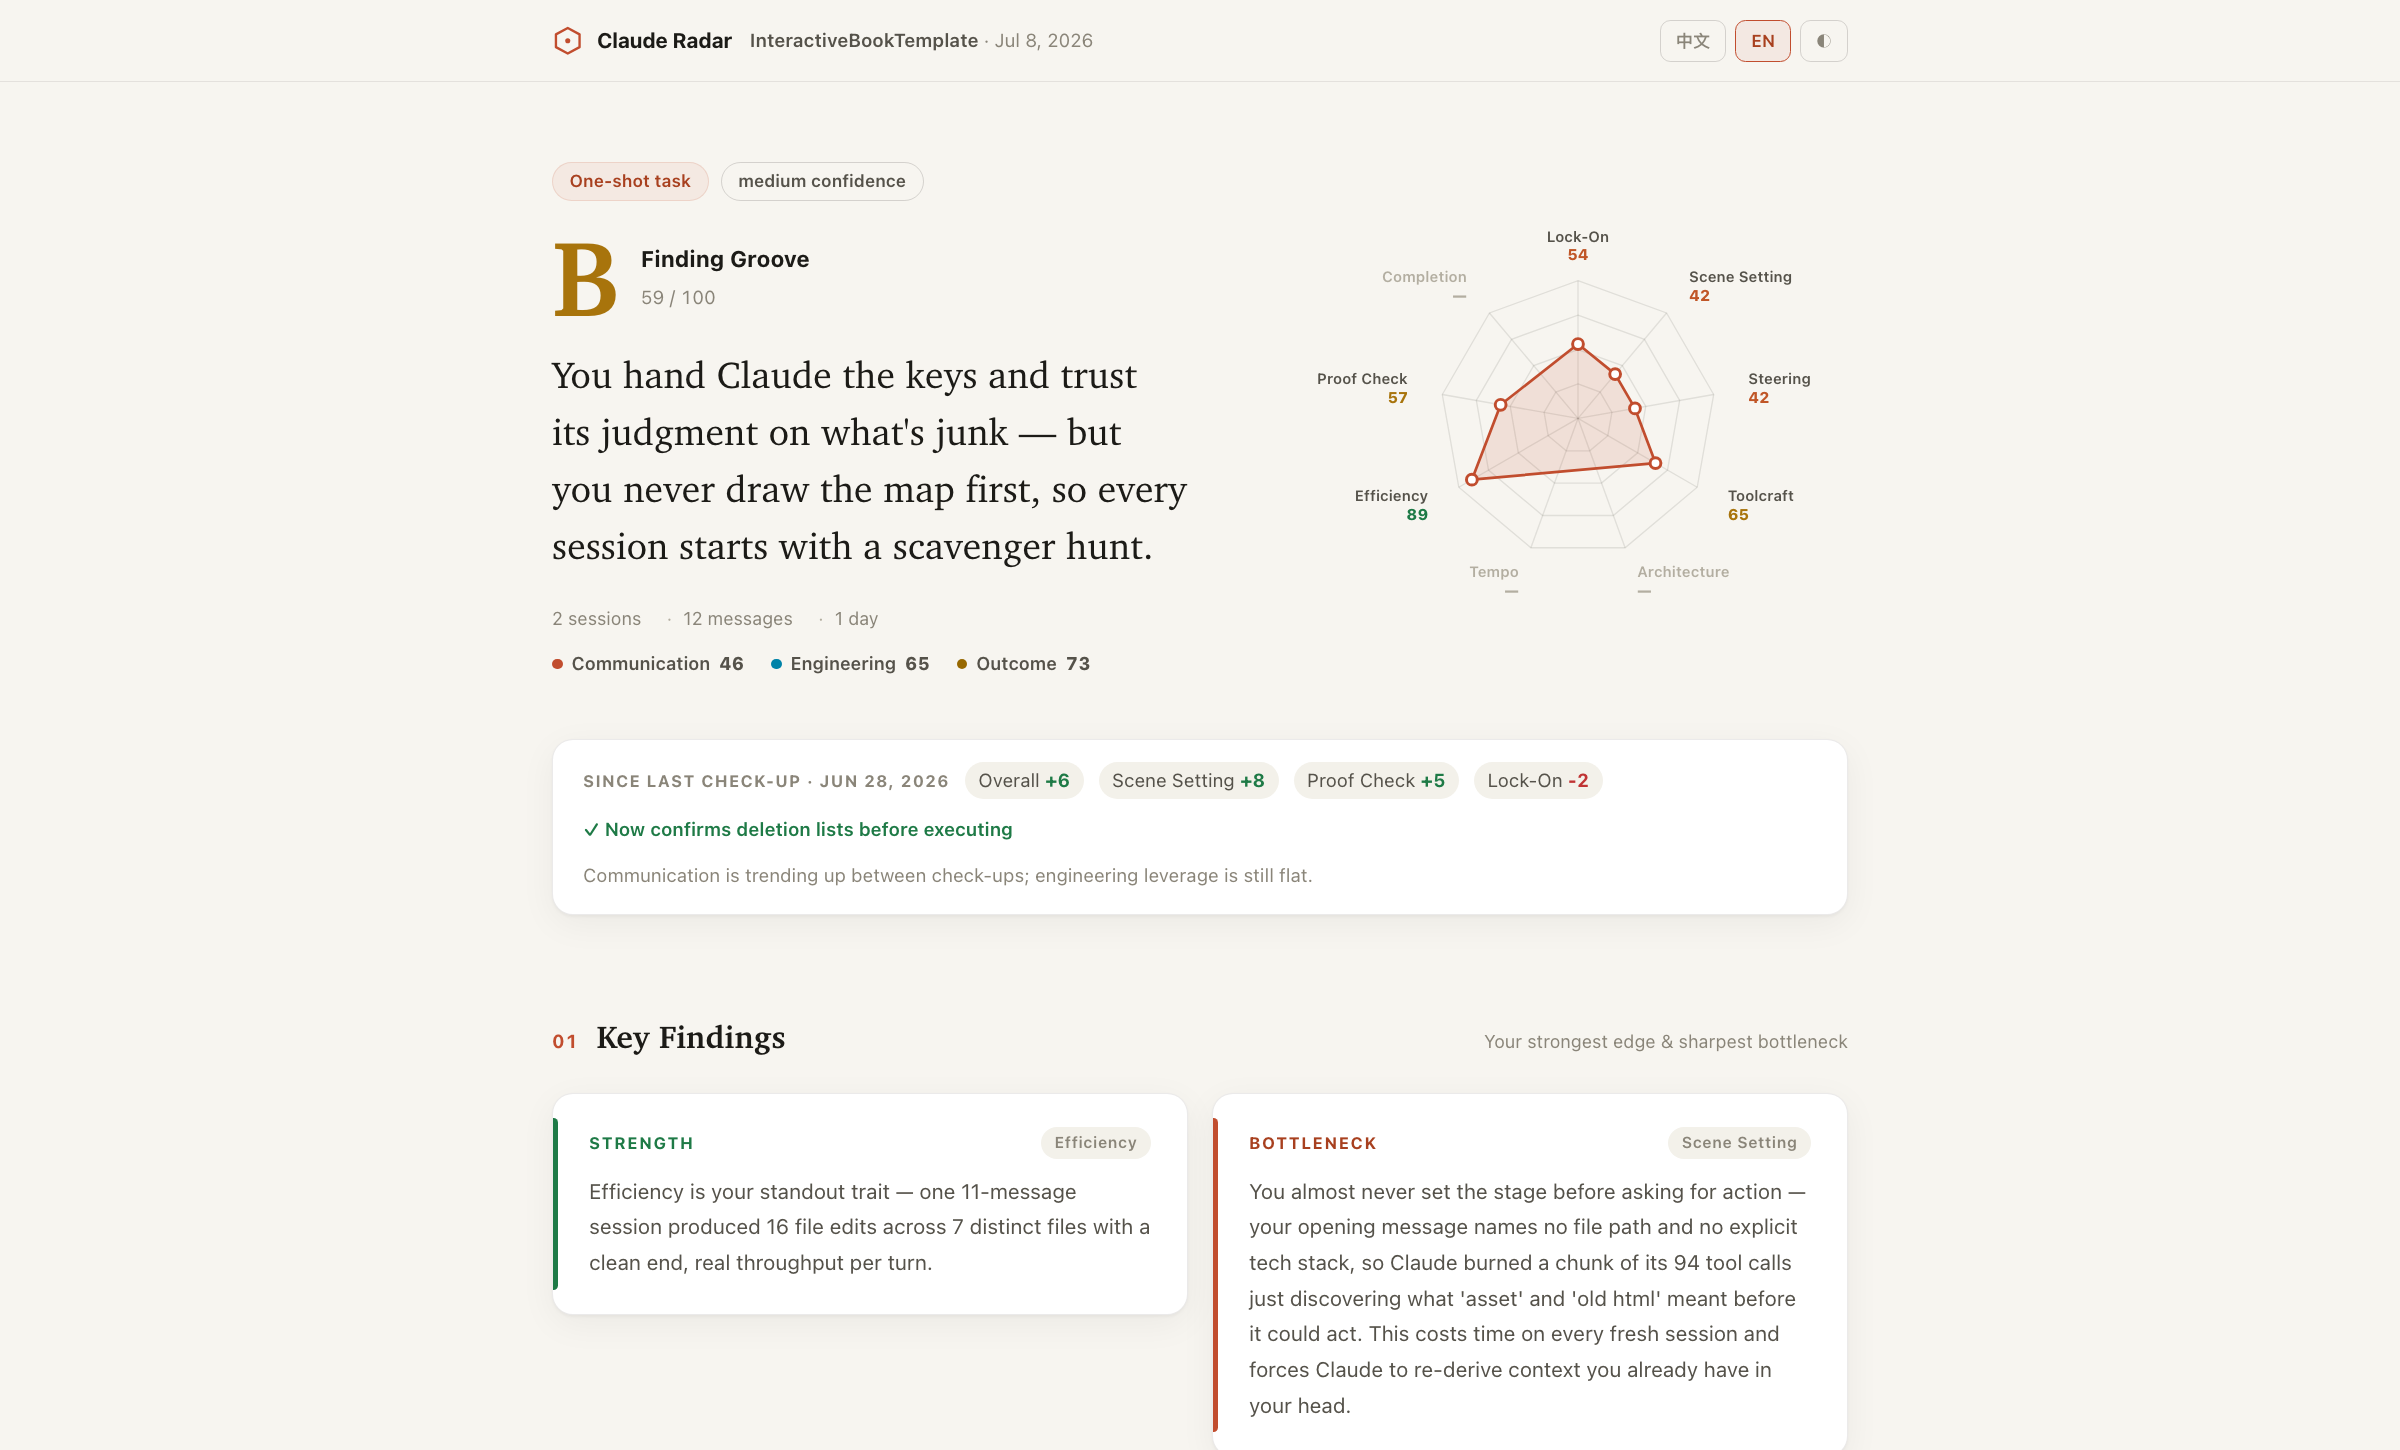
Walk away knowing what to change next
More than a score sheet. It tells you where you held things back, why, and exactly what to say instead — every line backed by evidence.
See how far you push Claude Code
Communication — how you direct AI. Engineering — how far you push platform leverage (Skill / MCP / Subagent / Workflow orchestration / parallel fan-out / background tasks / CLAUDE.md / hooks / Plan). Outcome — what you actually ship. 9 dimensions, 3 categories. Most people leave that leverage on the table: you're not docked for skipping advanced tools, only for using them badly — endless retries, Plans opened then abandoned.
Someone points out the problem for you
It's not a cold score sheet and done. You get a diagnosis written to your own collaboration habits: where you're strongest, what bottleneck holds you back most, and what several dimensions together reveal — every line citing real evidence from your sessions. This is the part users value most.
Suggestions you can paste back in — or install outright
Every suggestion comes with concrete wording you can paste straight into your next session, plus its expected impact. Setup suggestions go further and ship the actual file — a CLAUDE.md section, a hook config, an .mcp.json entry — ready to install. Reports are archived locally, so each new check-up shows your score deltas and which past suggestions you actually adopted. All in one single-file HTML, easy to forward to a teammate.
New in v1.3 — your verification loop counts, and autonomy gets measured
Verification is a loop, not a request. Test and build runs, reviewer subagents, browser and UI checks, hooks — Claude Radar credits the loop you built, even if you never typed "test it". And it now measures autonomy: how much of your work runs in long autonomous turns, whether you queue the next instruction instead of interrupting, how much you hand off to background agents. Manual compaction reads as deliberate tempo rather than a penalty, and the playbook skips the moves you're already making. Recalibrated by Claude Fable 5.1 for its own era.
Measured, not guessed
Every score traces back to specific signals in your session history. No black box, no vibes.
AI writes the diagnosis
Scores tell you what. Diagnosis tells you why and what to do next. Independent of scoring, evidence-grounded, no personality archetypes.
A 3-message bugfix is not a 50-session build
Every project is auto-classified into one of 4 profiles, each with its own dimension weights and N/A rules. Small projects no longer get unfairly penalized.
Three steps to your dashboard
Install
Add the marketplace
/plugin marketplace addRun
From your project directory
/claude-radarDashboard
Opens automatically in browser
single-file HTML100% on your machine
Your session data never leaves your computer. Ever.
Install
/plugin marketplace add lemomo-ai/claude-radar
/plugin install claude-radar@claude-radar-marketplace
/claude-radar
Or clone the repo and pass --plugin-dir to claude.